

Before you begin
Attribution answers what a conversion owes to a Reelevant interaction. Customer impact answers a different question: are the customers you personalise for worth more than comparable customers you do not personalise for, and through which behaviour. These measures require the purchase dataset configured as your attribution source in Analytics Settings to carry a customer identifier. Website purchase events are not enough: a browser only knows who the visitor is once they have identified themselves, so per-customer measures are rejected when your attribution source is web tracking rather than a purchase dataset.What is measured
Every measure is computed over the period you query, on the customers Reelevant reached over that period.
Orders are counted as transactions, not as order lines: a basket containing seven product references is one order.
The dashboard opens on the last three months. These measures compare cohorts of customers rather than displays, so a shorter period holds too few purchases per customer to read, and a period under a month is refused outright.
The comparison
Each measure is available on two populations, the Exposed Population and the Non-Exposed Population, through the Was Exposed dimension:
Both populations are drawn from the customers Reelevant reached, so the comparison is personalisation against the same channels without personalisation. Customers who never appear in your Workflow activity over the period belong to neither population, whatever your purchase data says about them.
Customers whose experience was only partly personalised — one personalised Content among many non-personalised ones — belong to neither population. They remain visible in the population counts, but they weigh on no comparison: counting them as exposed would describe an experience they did not have.Both thresholds are part of your reporting configuration, under Personalization exposure in Analytics Settings. Raise them when personalisation is the norm across your Workflows, lower them when only a few Contents are personalised.
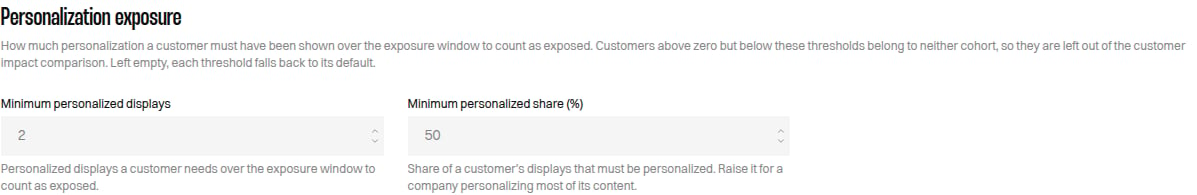
Left empty, each threshold falls back to its default. Changing either one redraws both populations, so the measures move: expect a stricter threshold to shrink the Exposed Population and to widen the differences.
The weighting matters. Customers who receive more personalisation tend to be more engaged, so they tend to be better customers before any personalisation happens. Reelevant therefore groups customers by decile of orders and decile of value over the preceding period, and weights the Non-Exposed Population so that each decile carries the same share as in the Exposed Population. The two populations then have, on average, the same purchasing history.
The uplift measures
Each uplift compares each population with its own preceding period, rather than comparing the two populations directly. Two effects then cancel out: a seasonal trend that affects everyone, and whatever difference the weighting could not close.
Cohort Pre-Period Gap is how you check the comparison rather than a result to report. On one retailer, weighting brings it below 1%, which is what makes the uplifts meaningful. A gap of more than a few percent means the two populations are not comparable enough and the uplifts should be read as indicative only.
Worked example
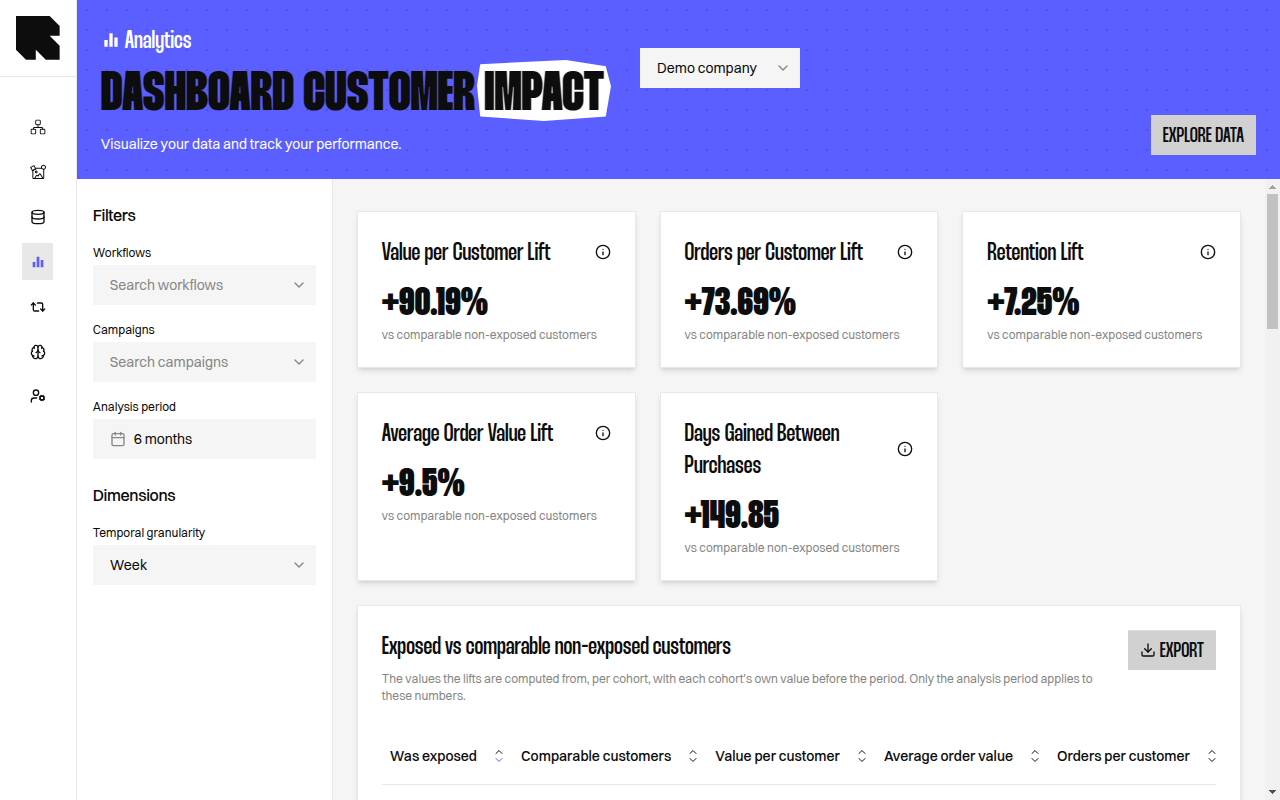
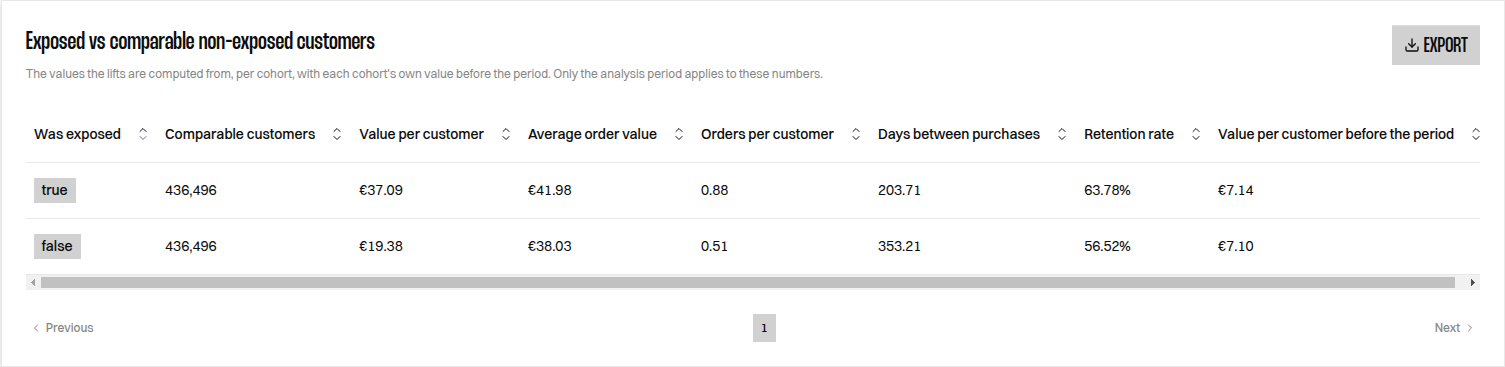
One retailer, six months, 436,496 comparable customers on each side:
Read the mechanism, not only the headline. Value per customer is up 90.2%, and most of it comes from customers ordering more often rather than spending more per order, which moves 9.5%. Retention is 7.3 points higher, so the gain is partly in holding on to established buyers and partly in how many of the reached customers buy at all. The pre-period gap of 0.6% is what makes the comparison usable.
Per set of Channels
Each Uplift measure breaks down per set of Channels the customers could be reached on, through the Reachable channels dimension. The account-wide figure then splits into one comparison per set:email, email + web, email + mobile + web, and so on.
This is a separate comparison rather than a slice of the account-wide one. Reachability is part of the matching key, so customers are only ever compared with customers reachable on the same Channels. Comparing an email + web customer with an email-only one measures the audience: a customer we can reach on the web is a customer browsing the site.
Each row reports whether its comparison can be read at all, and shows no figure when it cannot:
The two customer counts in the table are observed customers on each side, not the weighted population. A handful of non-exposed customers weighted onto a large exposed cohort reads as a handful, which is what makes a thin row recognisable.
Read the sets rather than the Channels. A customer reachable on email and on the web appears in
email + web only, never in email, so the rows partition your customers instead of overlapping. A Channel present in several sets has no single Uplift.When the comparison is refused
A cohort too small, or with no purchase history to grow from, produces an Uplift that moves with a single basket. Those figures are left empty rather than reported, and an empty Uplift is not a zero one.
The threshold counts observed customers on both sides, so the weighting cannot satisfy it. Raise it when your Uplifts move between two consecutive queries; lower it to read smaller sets of Channels, accepting noisier figures.
Where the difference came from
The Uplift measures say how much the two populations differ. The lifecycle matrix says where that difference sits, by following each customer from their lifecycle stage at the start of the period to their stage at the end.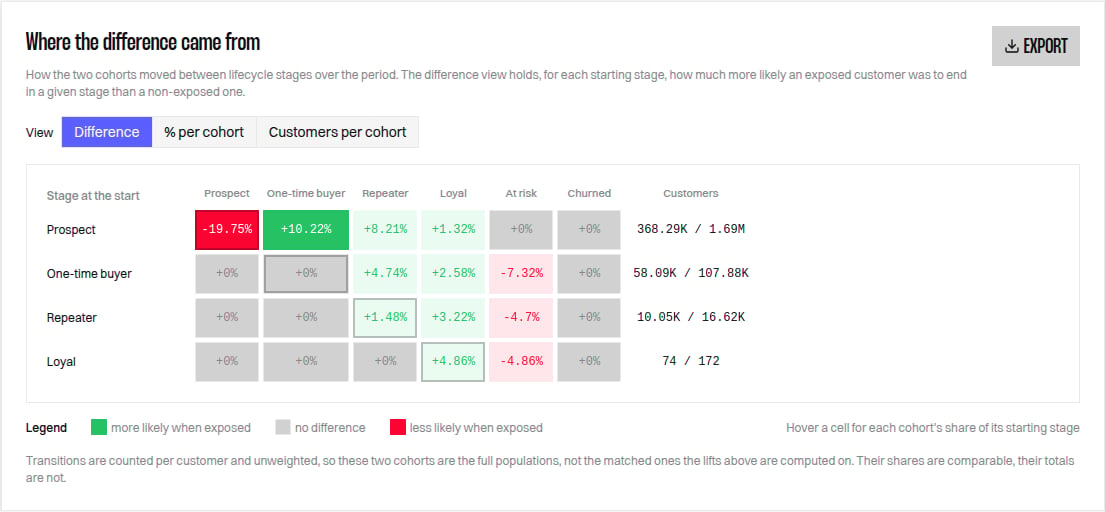
Read the difference view row by row. In the example above, 19.8 points fewer exposed customers stayed prospects, and those customers reappear as first purchases and repeat purchases, which is the mechanism behind the value and frequency measures.
The matrix is unweighted, so its two populations are the full ones rather than the matched populations behind the measures above. Shares are comparable between the two, totals are not. Partly personalised customers appear in neither.
Exposure pressure
Exposure Decile splits the Exposed Population into ten groups, from the least to the most exposed, so you can read value per customer and orders per customer against exposure volume. It answers whether more exposure keeps paying, and where returns flatten. Each decile also reports personalised Contents, impressions, clicks and distinct Contents seen. These values make each decile readable as received volume rather than only a rank.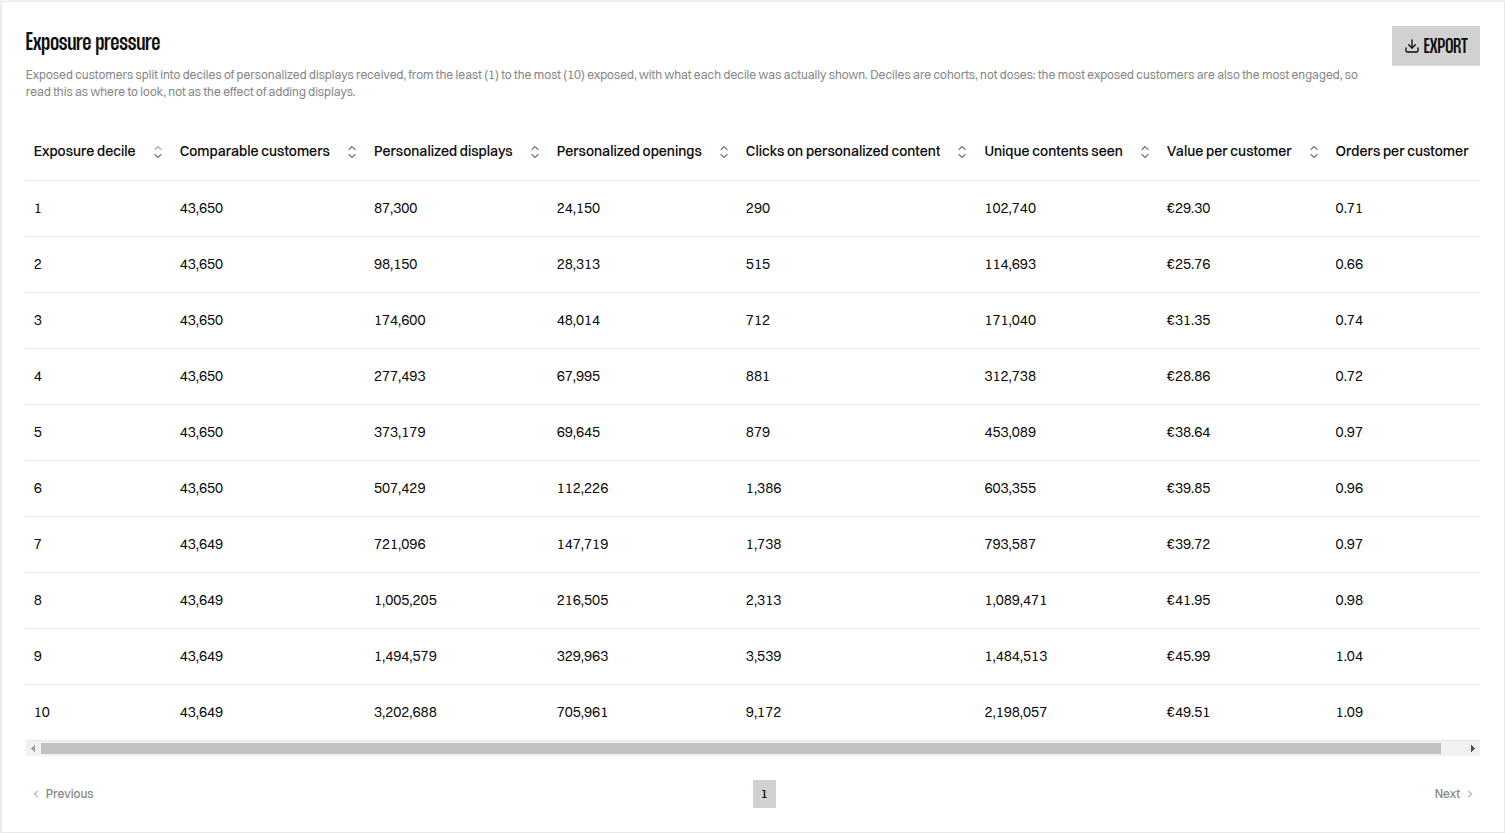
Read the pressure curve within the Exposed Population only. It is a dose-response reading and not a second comparison between the two populations: the most exposed customers are also the most active ones, and part of the curve reflects that rather than the effect of exposure.
How far these numbers go
Exposure is not randomised. Weighting makes the two populations comparable on their purchasing history, but not on reachability, consent or engagement, and those differences are not observable in the data.
Report it as the Exposed Population compared with a comparable Non-Exposed Population. A causal claim requires a randomised Non-Exposed Population, where a share of your reachable customers is deliberately never personalised.
Always read Comparable customers before reading any figure. Weighting only keeps customers whose buying history exists on both sides, so a small or very homogeneous population can leave nothing to compare. Those measures then read empty rather than 0, since “not computable” is not the same answer as “no effect”.
Both populations include customers who had never bought before the period, so a first purchase counts towards the uplifts. Value per customer before the period is then low on both sides, which makes it a balance check between the two populations rather than a figure to report.